V-GIFT: Boosting Visual Instruction Tuning with Self-Supervised Guidance
NeurIPS 2026
Abstract
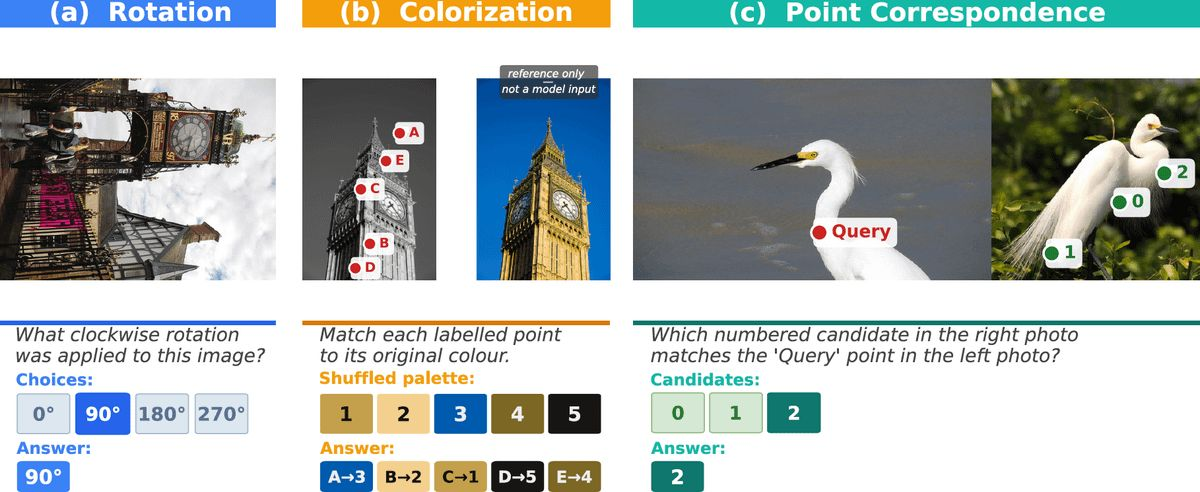
Multimodal large language models (MLLMs) often struggle with vision-centric tasks, revealing a gap between their language fluency and genuine visual understanding. We propose to augment instruction tuning with a small number of visually grounded self-supervised tasks expressed as natural language instructions. Classical pretext tasks such as rotation prediction, color matching, and cross-view correspondence are reformulated as image-instruction-response triplets, requiring no human annotations or architectural changes. Injecting 3-10% of such visually grounded instructions consistently improves performance on vision-centric benchmarks across multiple models and training regimes, offering a simple and effective recipe for strengthening the visual grounding of MLLMs.
BibTeX
@inproceedings{sirkogalouchenko2026vgift,
  title     = {V-GIFT: Boosting Visual Instruction Tuning with Self-Supervised Guidance},
  author    = {Sirko-Galouchenko, Sophia and Wysoczanska, Monika and Bursuc, Andrei and Thome, Nicolas and Gidaris, Spyros},
  booktitle = {Advances in Neural Information Processing Systems (NeurIPS)},
  year      = {2026}
}